
Hello, arXiv visitor 👋
Welcome to Replicate. We're making it easy to share your machine learning model. Check out some recently featured models:
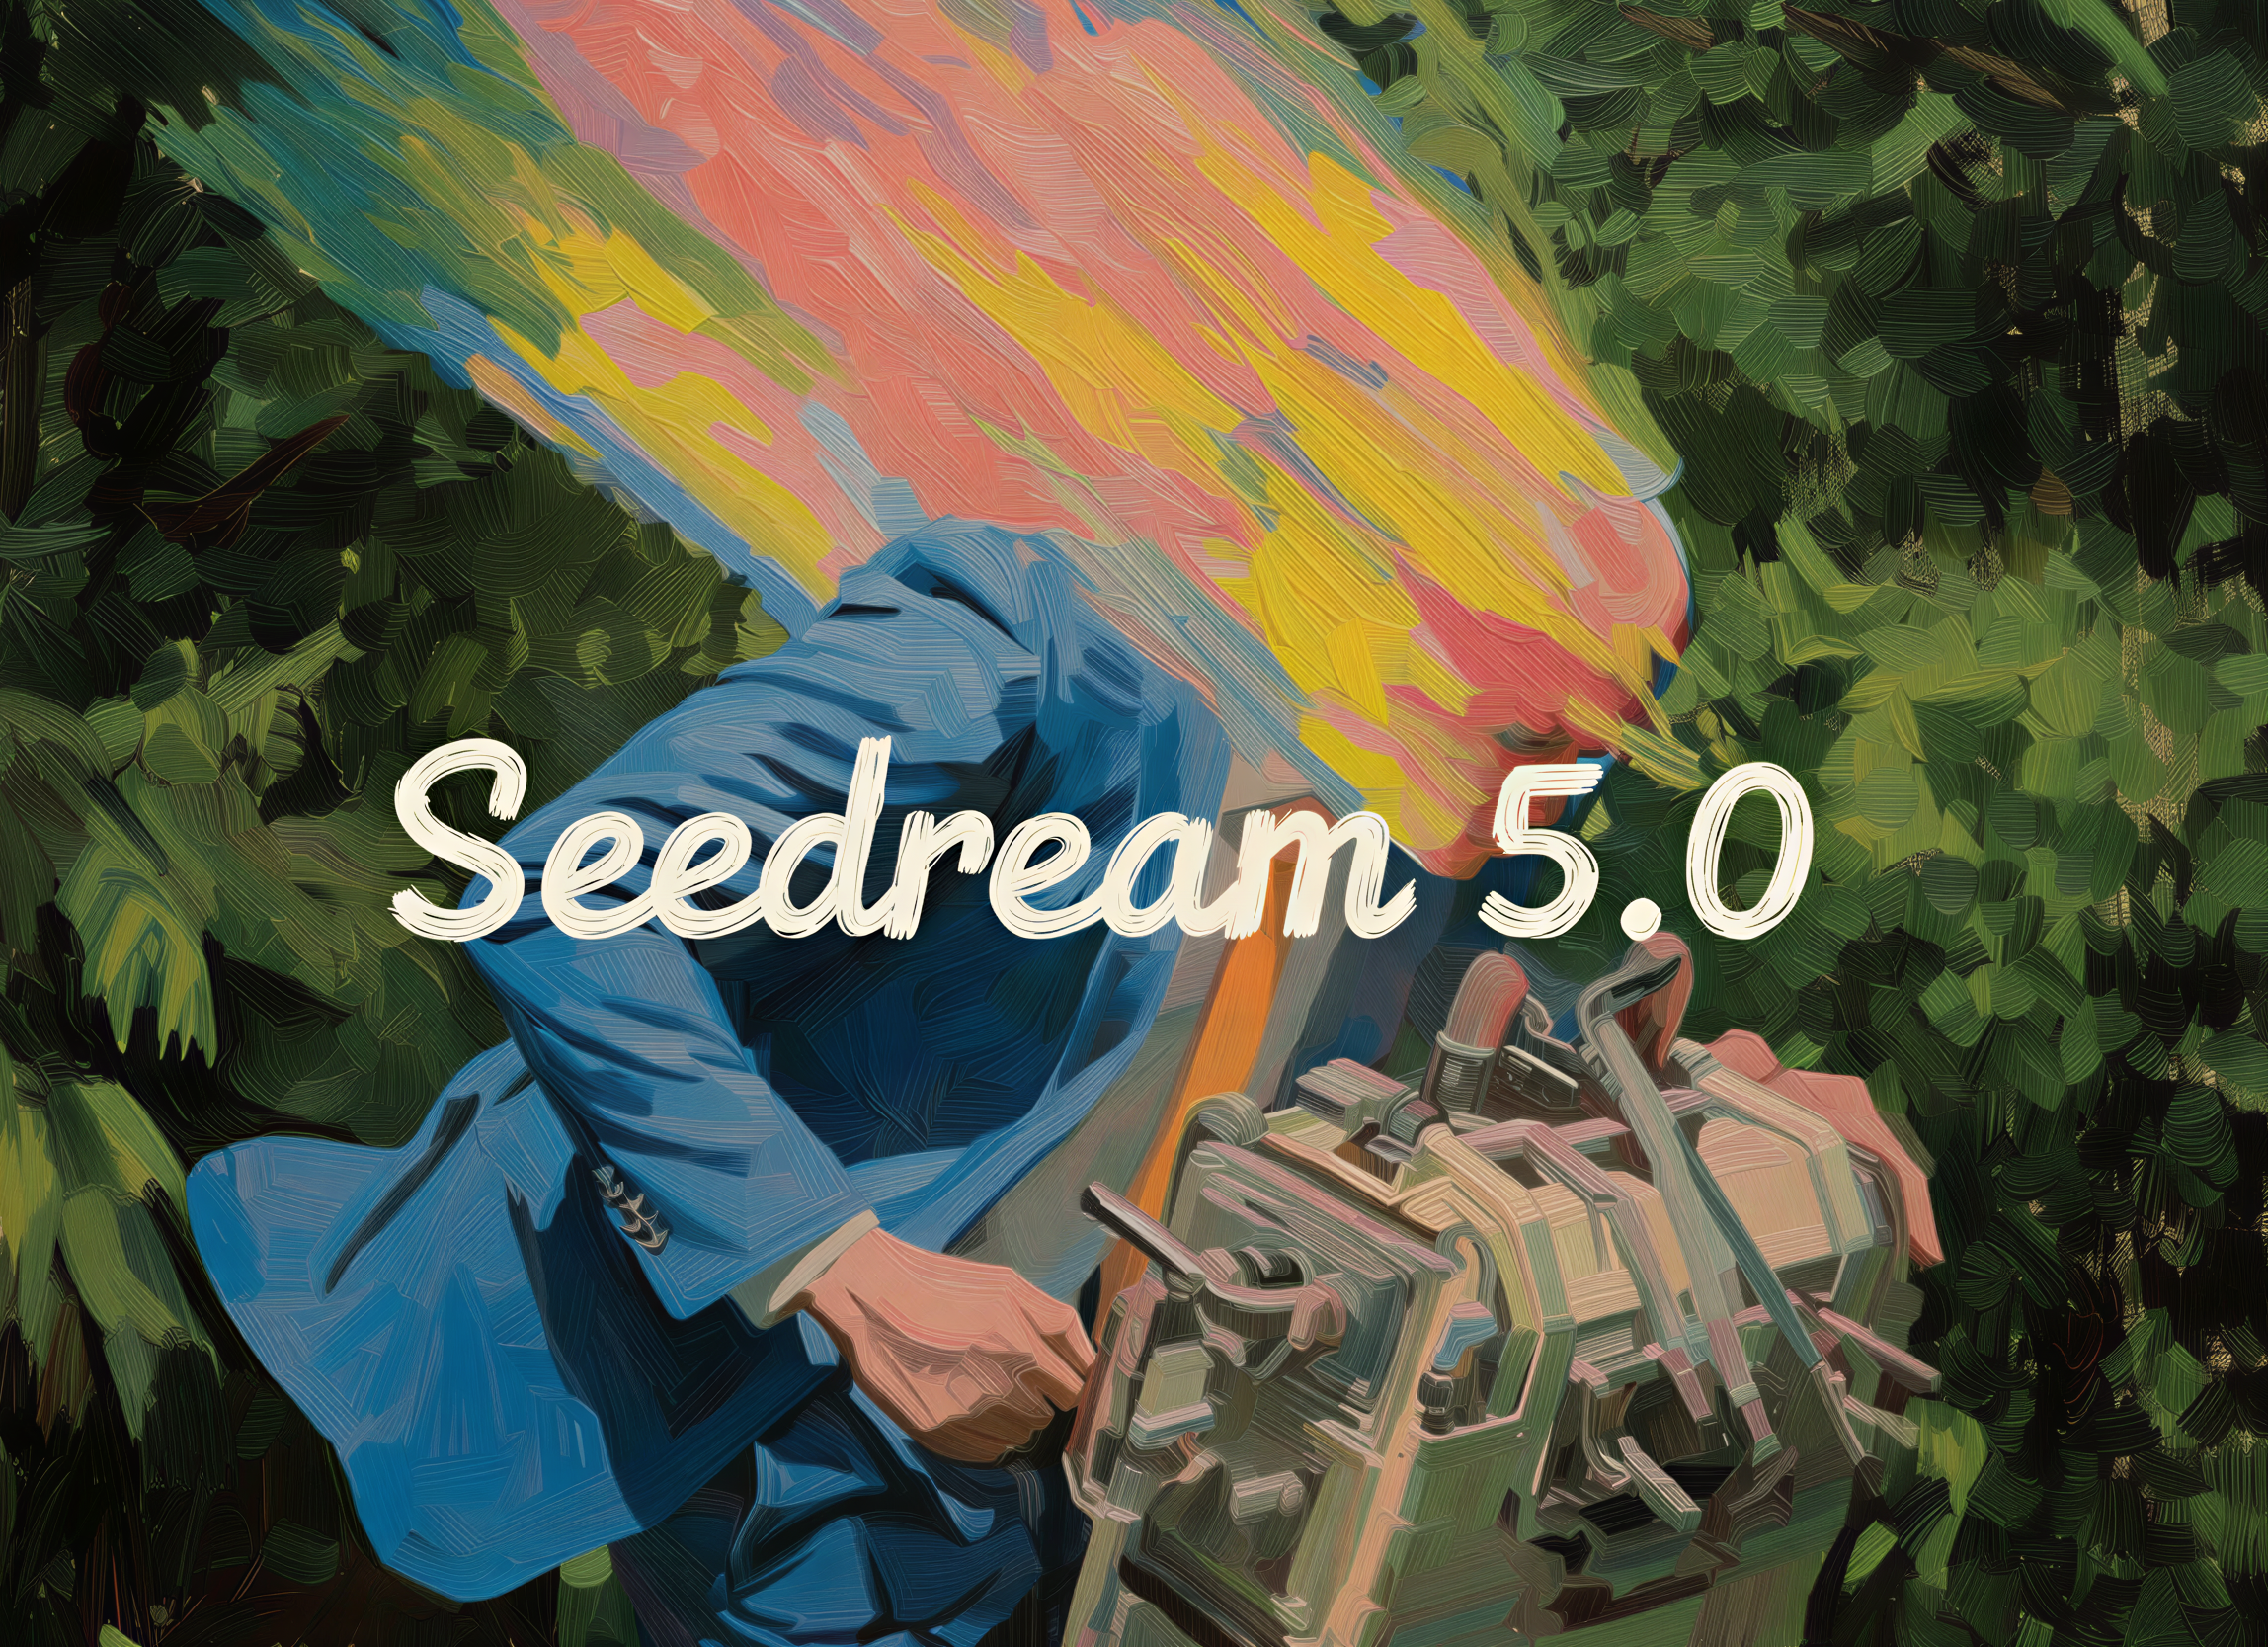
bytedance / seedream-5-lite
Seedream 5.0 lite is ByteDance's image model with built-in reasoning, example-based editing, and deep domain knowledge.
inworld / realtime-tts-2
Inworld's most expressive text-to-speech model, with natural-language steering, real-time latency, and support for more than 100 languages.
minimax / h3-highspeed
Generate videos with MiniMax H3 Highspeed, a faster version of MiniMax H3 that balances quality and speed. Supports text-to-video, first- and last-frame image-to-video, and reference-based video generation at 768P.
Share your model
If this is your first time creating a model, have a look at the docs, otherwise go ahead and create a new model.
